



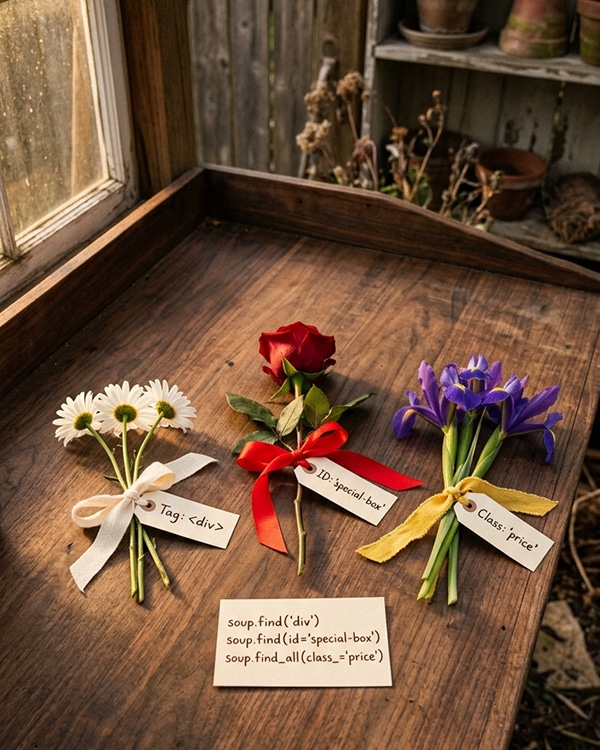
To scrape data effectively, you need to locate the right elements. You might want all products (each in a div class=”product”). You might want the main content area (div id=”main”). You might want all images (img tags). You might want all links (a tags with href).
This lesson focuses on the practical skills of targeting elements by tags, classes, IDs, and other attributes. You will learn to combine these selectors to pinpoint exactly the data you need, even in complex, nested HTML structures.
🕯️ Magic Note
In a typical HTML page, there are hundreds or thousands of elements. The art of web scraping is not parsing HTML—it is identifying the right elements. Inspect elements in your browser’s Developer Tools (F12) to find the patterns you need.
Python
from bs4 import BeautifulSoup
html = “””
<html>
<body>
<h1>Page Title</h1>
<p>First paragraph.</p>
<p>Second paragraph.</p>
<a href=”/page1″>Page 1</a>
<a href=”/page2″>Page 2</a>
<img src=”image.jpg” alt=”Example”>
</body>
</html>
“””
soup = BeautifulSoup(html, “html.parser”)
# Get first occurrence of a tag
first_p = soup.p
print(f”First p: {first_p.text}”)
first_a = soup.a
print(f”First a: {first_a.get(‘href’)}”)
# Get all occurrences
all_p = soup.find_all(“p”)
print(f”All p tags: {len(all_p)}”)
all_links = soup.find_all(“a”)
for link in all_links:
print(f”Link: {link.get(‘href’)} – {link.text}”)
# Multiple tag types at once
headers_and_paragraphs = soup.find_all([“h1”, “p”])
print(f”Headers and paragraphs: {len(headers_and_paragraphs)}”)
Python
from bs4 import BeautifulSoup
html = “””
<div id=”header”>
<h1>Website Title</h1>
</div>
<div id=”main-content”>
<p>This is the main content.</p>
<div id=”sidebar”>
<p>Sidebar content.</p>
</div>
</div>
<div id=”footer”>
<p>Footer text.</p>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Find by ID using find()
header = soup.find(id=”header”)
print(f”Header: {header.h1.text}”)
main_content = soup.find(id=”main-content”)
print(f”Main content p: {main_content.find(‘p’).text}”)
# Find by ID using CSS selector
footer = soup.select_one(“#footer”)
print(f”Footer: {footer.p.text}”)
# IDs are unique – find_all with ID returns one element (or empty list)
sidebar = soup.find_all(id=”sidebar”)
if sidebar:
print(“Sidebar found”)
🕯️ Magic Note
An ID should be unique on the page. If you find an element with a specific ID, you can be confident you have the right element. IDs are the most reliable selectors for web scraping.
Python
from bs4 import BeautifulSoup
html = “””
<div class=”product”>
<h2>Product 1</h2>
<p class=”price”>$19.99</p>
<p class=”description”>Great product.</p>
</div>
<div class=”product”>
<h2>Product 2</h2>
<p class=”price”>$29.99</p>
<p class=”description”>Even better product.</p>
</div>
<div class=”product sale”>
<h2>Product 3</h2>
<p class=”price”>$39.99</p>
<p class=”discount”>20% off!</p>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Find by class (first element)
first_product = soup.find(class_=”product”)
print(f”First product: {first_product.h2.text}”)
# Find all elements with a class
all_products = soup.find_all(class_=”product”)
print(f”Total products: {len(all_products)}”)
# Find elements with multiple classes
sale_products = soup.find_all(class_=”product sale”)
print(f”Products with both classes: {len(sale_products)}”)
# Find by class using CSS selector
prices = soup.select(“.price”)
for price in prices:
print(f”Price: {price.text}”)
# Find by combination of tag and class
product_descriptions = soup.find_all(“p”, class_=”description”)
for desc in product_descriptions:
print(f”Description: {desc.text}”)
Python
from bs4 import BeautifulSoup
html = “””
<div>
<a href=”https://example.com/page1″>Link 1</a>
<a href=”/page2″>Link 2</a>
<a href=”https://google.com” target=”_blank”>Google</a>
<img src=”image1.jpg” alt=”First image”>
<img src=”image2.jpg” alt=”Second image” width=”100″>
<div data-product-id=”123″ data-category=”books”>Book</div>
<div data-product-id=”456″ data-category=”electronics”>Laptop</div>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Find by any attribute
external_links = soup.find_all(“a”, attrs={“href”: re.compile(r”^https://”)})
for link in external_links:
print(f”External: {link.get(‘href’)}”)
images = soup.find_all(“img”)
for img in images:
src = img.get(“src”)
alt = img.get(“alt”, “No alt text”)
print(f”Image: {src} – {alt}”)
# Find by data-* attributes
book_div = soup.find(attrs={“data-product-id”: “123”})
print(f”Product: {book_div.text}”)
# Find by attribute existence
links_with_target = soup.find_all(“a”, attrs={“target”: True})
for link in links_with_target:
print(f”Link with target: {link.get(‘href’)}”)
# CSS selector for attributes
electronics = soup.select(“[data-category=’electronics’]”)
if electronics:
print(f”Category: {electronics[0].text}”)
Python
from bs4 import BeautifulSoup
import re
html = “””
<div id=”products”>
<div class=”product-item” data-id=”1″>
<h3>Python Book</h3>
<p class=”price”>$29.99</p>
<a href=”/products/1″ class=”details”>View Details</a>
</div>
<div class=”product-item featured” data-id=”2″>
<h3>Web Scraping Guide</h3>
<p class=”price”>$39.99</p>
<a href=”/products/2″ class=”details”>View Details</a>
</div>
<div class=”product-item” data-id=”3″>
<h3>Data Analysis with Python</h3>
<p class=”price”>$49.99</p>
<a href=”/products/3″ class=”details”>View Details</a>
</div>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Combine ID and class
products_container = soup.select_one(“#products”)
product_items = products_container.find_all(class_=”product-item”)
print(f”Products in container: {len(product_items)}”)
# Combine tag and class
prices = soup.find_all(“p”, class_=”price”)
for price in prices:
print(f”Price: {price.text}”)
# CSS selector with multiple conditions
featured_products = soup.select(“.product-item.featured”)
print(f”Featured products: {len(featured_products)}”)
# CSS selector with attribute
product_links = soup.select(“.product-item .details”)
for link in product_links:
print(f”Product link: {link.get(‘href’)}”)
# CSS selector with child relationship
prices_inside_products = soup.select(“#products .product-item .price”)
print(f”Prices inside products: {len(prices_inside_products)}”)
🕯️ Magic Note
CSS selectors are often more concise than nested find() calls. A selector like “#products .product-item .price” is a single line that expresses a complex path: from the element with ID ‘products’, find any element with class ‘product-item’ inside it, and inside that, find elements with class ‘price’.
Python
from bs4 import BeautifulSoup
import re
html = “””
<div>
<a href=”https://example.com/doc1.pdf”>Document 1</a>
<a href=”https://example.com/doc2.pdf”>Document 2</a>
<a href=”https://example.com/image.jpg”>Image</a>
<a href=”https://google.com”>Google</a>
<div class=”user-card-123″>User 123</div>
<div class=”user-card-456″>User 456</div>
<div class=”admin-card-789″>Admin 789</div>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Find links ending with .pdf
pdf_links = soup.find_all(“a”, href=re.compile(r”\.pdf$”))
for link in pdf_links:
print(f”PDF: {link.get(‘href’)}”)
# Find links from a specific domain
internal_links = soup.find_all(“a”, href=re.compile(r”^https://example\.com”))
print(f”Internal links: {len(internal_links)}”)
# Find divs with class starting with “user-card”
user_cards = soup.find_all(“div”, class_=re.compile(r”^user-card”))
for card in user_cards:
print(f”User card: {card.text}”)
# CSS selector with regex (using lambda)
cards = soup.find_all(lambda tag: tag.name == “div” and re.search(r”card-\d+”, tag.get(“class”, [“”])[0]))
for card in cards:
print(f”Card: {card.text}”)
| Selector | What It Selects | Example |
|---|---|---|
| tag | All elements with that tag | p |
| #id | Element with specific ID | #main |
| .class | Elements with specific class | .product |
| tag.class | Tags with specific class | div.product |
| parent child | Child elements (any depth) | div p |
| parent > child | Direct children only | div > p |
| tag1, tag2 | Multiple selectors (OR) | h1, h2 |
| [attribute] | Elements with attribute | [href] |
| [attribute=”value”] | Exact attribute match | [type=”text”] |
| [attribute^=”value”] | Starts with value | [href^=”https”] |
| [attribute$=”value”] | Ends with value | [href$=”.pdf”] |
| [attribute*=”value”] | Contains value | [class*=”product”] |
Python
from bs4 import BeautifulSoup
html = “””
<div id=”container”>
<ul class=”menu”>
<li><a href=”/home”>Home</a></li>
<li><a href=”/about” class=”active”>About</a></li>
<li><a href=”/contact”>Contact</a></li>
</ul>
<div class=”content”>
<div class=”article”>
<h2>Article 1</h2>
<p>Content here.</p>
</div>
</div>
</div>
“””
soup = BeautifulSoup(html, “html.parser”)
# Tag selector
divs = soup.select(“div”)
# ID selector
container = soup.select_one(“#container”)
# Class selector
articles = soup.select(“.article”)
# Descendant selector (any depth)
all_links = soup.select(“#container a”)
# Child selector (direct children only)
direct_children = soup.select(“#container > ul”)
# Attribute selector
active_link = soup.select_one(“a[class=’active’]”)
# Multiple selectors (OR)
headers = soup.select(“h1, h2, h3”)
Python
from bs4 import BeautifulSoup
import re
import json
def extract_products(html_content):
“””Extract product information from HTML.”””
soup = BeautifulSoup(html_content, “html.parser”)
products = []
# Find all product containers
product_divs = soup.find_all(“div”, class_=re.compile(r”product|item”))
for div in product_divs:
product = {}
# Extract product ID from data attribute
product_id = div.get(“data-id”) or div.get(“data-product-id”)
if product_id:
product[“id”] = product_id
# Extract name (various possible selectors)
name_selectors = [“h2”, “h3”, “.product-name”, “.title”, “[data-name]”]
for selector in name_selectors:
name_elem = div.select_one(selector)
if name_elem:
product[“name”] = name_elem.text.strip()
break
# Extract price
price_elem = div.select_one(“.price, [data-price], .product-price”)
if price_elem:
price_text = price_elem.text.strip()
# Extract numeric price using regex
match = re.search(r”\d+(?:\.\d{2})?”, price_text)
if match:
product[“price”] = float(match.group())
# Extract link
link_elem = div.select_one(“a[href]”)
if link_elem:
product[“url”] = link_elem.get(“href”)
# Extract description (if present)
desc_elem = div.select_one(“.description, .product-description, p”)
if desc_elem and desc_elem not in price_elem if price_elem else True:
product[“description”] = desc_elem.text.strip()[:200]
if product: # Only add if we found something
products.append(product)
return products
- Assuming classes are unique (they are not; use IDs for uniqueness)
- Using overly broad selectors that match too many elements
- Not handling missing attributes (causes AttributeError)
- Forgetting that class_ parameter requires underscore (versus class in HTML)
- Assuming element order when scraping (pages may change)
- Hard-coding selectors that are likely to change (use more stable selectors like IDs)
- What is the difference between finding by ID and finding by class?
- Write a CSS selector that finds all <p> tags inside a <div class=”content”>.
- How do you find an element with a specific data-product-id attribute?
- What is the advantage of using IDs over classes for scraping?
- Write a selector that finds all links that start with “https://”
- How do you find all elements that have both “product” and “featured” classes?
⚡ Whisper
The web is a forest of tags. Each element is a leaf. Some leaves have unique IDs—one in the whole forest. Some leaves share classes—a whole branch of similar leaves. Some have no markers at all. Your task is to find the right leaves. You learn to see patterns. Products live in div class=”product”. Prices hide in span class=”price”. Images wait in img tags. You become a detective. Inspect with browser tools. Look for IDs first—they are your best friends. Then classes—they group the similar. Then attributes—they hold extra clues. Combine selectors to pinpoint exactly what you need. A single div.product .price might extract all the prices from all the products. That is the art. That is the skill. Practice on real pages. The patterns will emerge. And the data will come.


