



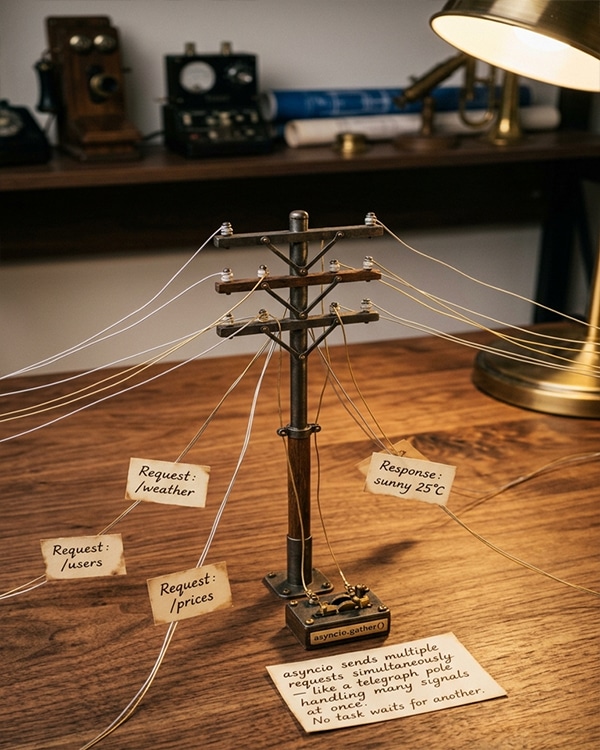
What if you could fetch all 100 at the same time? The total time would be just over 1 second. This is asynchronous programming.
In this experiment, you will build a concurrent web scraper using Python’s `asyncio` and `aiohttp`. You will scrape multiple websites at once, handle errors gracefully, respect rate limits, and save the results. This is not a theoretical lesson. It is a hands-on project that solves a real problem: scraping many pages efficiently.
🕯️ Magic Note
asyncio is not faster for CPU-heavy tasks. It excels at I/O-bound tasks like network requests. Your scraper spends most of its time waiting for servers to respond. asyncio uses that waiting time to start other requests. This is concurrency, not parallelism. And it is perfect for web scraping.
- Fetch 50+ URLs concurrently (not one by one)
- Handle network errors and timeouts gracefully
- Respect robots.txt and rate limits
- Save scraped data to JSON and CSV
- Measure the speed improvement over synchronous scraping
Bash
# Create and activate virtual environment
python -m venv scraper_env
source scraper_env/bin/activate # Windows: scraper_env\Scripts\activate
# Install required libraries
pip install aiohttp beautifulsoup4 aiofiles
Python (sync_scraper.py – for comparison)
import requests
import time
urls = [
“https://example.com”,
“https://httpbin.org/get”,
# … add 10-20 more URLs
]
def fetch_sync(url):
print(f”Fetching {url}…”)
response = requests.get(url, timeout=10)
print(f”Finished {url} (status: {response.status_code})”)
return response.text
start = time.perf_counter()
for url in urls:
fetch_sync(url)
elapsed = time.perf_counter() – start
print(f”\\nSynchronous scraping took {elapsed:.2f} seconds”)
# 10 URLs = ~10 seconds (sequential)
Python (async_scraper.py)
import asyncio
import aiohttp
import time
async def fetch_url(session, url):
“””Fetch a single URL asynchronously.”””
try:
async with session.get(url, timeout=aiohttp.ClientTimeout(total=10)) as response:
status = response.status
html = await response.text()
print(f”✓ {url} – status: {status}, length: {len(html)} chars”)
return {“url”: url, “status”: status, “html”: html, “error”: None}
except asyncio.TimeoutError:
print(f”✗ {url} – TIMEOUT”)
return {“url”: url, “status”: None, “html”: None, “error”: “Timeout”}
except aiohttp.ClientError as e:
print(f”✗ {url} – CLIENT ERROR: {e}”)
return {“url”: url, “status”: None, “html”: None, “error”: str(e)}
async def scrape_all(urls, max_concurrent=10):
“””Scrape all URLs concurrently with a limit on concurrent requests.”””
connector = aiohttp.TCPConnector(limit=max_concurrent)
async with aiohttp.ClientSession(connector=connector) as session:
tasks = [fetch_url(session, url) for url in urls]
results = await asyncio.gather(*tasks)
return results
async def main():
urls = [
“https://example.com”,
“https://httpbin.org/get”,
“https://jsonplaceholder.typicode.com/posts/1”,
“https://api.github.com/users/octocat”,
# Add 10-20 more URLs for a real test
]
print(f”Scraping {len(urls)} URLs concurrently…”)
start = time.perf_counter()
results = await scrape_all(urls, max_concurrent=10)
elapsed = time.perf_counter() – start
successful = sum(1 for r in results if r[“error”] is None)
print(f”\\nCompleted in {elapsed:.2f} seconds”)
print(f”Successful: {successful}/{len(urls)}”)
return results
if __name__ == “__main__”:
results = asyncio.run(main())
🕯️ Magic Note
The `TCPConnector(limit=max_concurrent)` controls how many simultaneous connections are made. Start with 10-20. Too high may get you rate-limited or banned. Too low reduces speed. Find the sweet spot for your target website.
Python (async_scraper_with_parse.py)
import asyncio
import aiohttp
from bs4 import BeautifulSoup
import time
async def fetch_and_parse(session, url):
“””Fetch a URL and extract title and meta description.”””
try:
async with session.get(url, timeout=aiohttp.ClientTimeout(total=10)) as response:
if response.status != 200:
return {“url”: url, “error”: f”HTTP {response.status}”}
html = await response.text()
soup = BeautifulSoup(html, “html.parser”)
title = soup.find(“title”)
title_text = title.text.strip() if title else “No title”
meta_desc = soup.find(“meta”, attrs={“name”: “description”})
description = meta_desc.get(“content”, “”)[:200] if meta_desc else “”
print(f”✓ {url[:50]}… – {title_text[:50]}”)
return {
“url”: url,
“title”: title_text,
“description”: description,
“status”: response.status,
“error”: None
}
except asyncio.TimeoutError:
return {“url”: url, “error”: “Timeout”}
except Exception as e:
return {“url”: url, “error”: str(e)}
async def main():
urls = [
“https://python.org”,
“https://github.com”,
“https://stackoverflow.com”,
# Add your own list of URLs
]
connector = aiohttp.TCPConnector(limit=10)
async with aiohttp.ClientSession(connector=connector) as session:
tasks = [fetch_and_parse(session, url) for url in urls]
results = await asyncio.gather(*tasks)
return results
if __name__ == “__main__”:
results = asyncio.run(main())
# Print summary
print(“\\n” + “=” * 50)
print(“SUMMARY”)
print(“=” * 50)
for r in results:
if r[“error”]:
print(f”❌ {r[‘url’]}: {r[‘error’]}”)
else:
print(f”✅ {r[‘title’]} ({r[‘url’]})”)
Python (save_results.py)
import json
import csv
import aiofiles
import asyncio
async def save_to_json(data, filename=”scraped_data.json”):
“””Save scraped data to JSON file asynchronously.”””
async with aiofiles.open(filename, “w”, encoding=”utf-8″) as f:
await f.write(json.dumps(data, indent=2, ensure_ascii=False))
print(f”Saved {len(data)} records to {filename}”)
def save_to_csv_sync(data, filename=”scraped_data.csv”):
“””Save scraped data to CSV file.”””
if not data:
return
fieldnames = data[0].keys()
with open(filename, “w”, newline=””, encoding=”utf-8″) as f:
writer = csv.DictWriter(f, fieldnames=fieldnames)
writer.writeheader()
writer.writerows(data)
print(f”Saved {len(data)} records to {filename}”)
# Add this to your main function:
# await save_to_json(results)
# save_to_csv_sync([r for r in results if not r[“error”]])
Python (rate_limited_scraper.py)
import asyncio
import aiohttp
class PoliteScraper:
def __init__(self, requests_per_second=2):
self.delay = 1.0 / requests_per_second
self._semaphore = asyncio.Semaphore(requests_per_second * 2)
self._last_request_time = 0
async def rate_limit(self):
“””Ensure we don’t exceed the rate limit.”””
now = asyncio.get_event_loop().time()
elapsed = now – self._last_request_time
if elapsed < self.delay:
await asyncio.sleep(self.delay – elapsed)
self._last_request_time = asyncio.get_event_loop().time()
async def fetch(self, session, url):
async with self._semaphore:
await self.rate_limit()
try:
async with session.get(url) as response:
return await response.text()
except Exception as e:
return None
# Usage
async def main():
scraper = PoliteScraper(requests_per_second=2) # 2 requests per second max
async with aiohttp.ClientSession() as session:
tasks = [scraper.fetch(session, url) for url in urls]
results = await asyncio.gather(*tasks)
return results
Python (complete_scraper.py)
import asyncio
import aiohttp
from bs4 import BeautifulSoup
import json
import time
from typing import List, Dict
class AsyncWebScraper:
def __init__(self, max_concurrent=10, rate_limit=5):
self.max_concurrent = max_concurrent
self.rate_limit = rate_limit
self._semaphore = asyncio.Semaphore(max_concurrent)
self._request_delay = 1.0 / rate_limit
self._last_request = 0
self.results = []
self.completed = 0
async def _rate_limit(self):
now = time.perf_counter()
elapsed = now – self._last_request
if elapsed < self._request_delay:
await asyncio.sleep(self._request_delay – elapsed)
self._last_request = time.perf_counter()
async def fetch_url(self, session: aiohttp.ClientSession, url: str) -> Dict:
async with self._semaphore:
await self._rate_limit()
try:
async with session.get(url, timeout=aiohttp.ClientTimeout(total=15)) as resp:
html = await resp.text()
soup = BeautifulSoup(html, “html.parser”)
title = soup.find(“title”)
self.completed += 1
print(f”[{self.completed}] ✓ {url[:60]}…”)
return {
“url”: url,
“status”: resp.status,
“title”: title.text.strip() if title else None,
“length”: len(html)
}
except asyncio.TimeoutError:
self.completed += 1
print(f”[{self.completed}] ✗ TIMEOUT {url[:60]}…”)
return {“url”: url, “error”: “Timeout”}
except Exception as e:
self.completed += 1
print(f”[{self.completed}] ✗ ERROR {url[:60]}…: {e}”)
return {“url”: url, “error”: str(e)}
async def scrape(self, urls: List[str]) -> List[Dict]:
self.results = []
self.completed = 0
connector = aiohttp.TCPConnector(limit=self.max_concurrent)
async with aiohttp.ClientSession(connector=connector) as session:
tasks = [self.fetch_url(session, url) for url in urls]
self.results = await asyncio.gather(*tasks)
return self.results
async def main():
# Example: scrape Hacker News front page links
urls = [
“https://news.ycombinator.com”,
“https://www.python.org”,
“https://realpython.com”,
“https://github.com/trending”,
# Add more URLs here
]
scraper = AsyncWebScraper(max_concurrent=5, rate_limit=3)
start = time.perf_counter()
results = await scraper.scrape(urls)
elapsed = time.perf_counter() – start
print(f”\\n{‘=’*50}”)
print(f”SCRAPING COMPLETE”)
print(f”{‘=’*50}”)
print(f”URLs attempted: {len(urls)}”)
print(f”Time taken: {elapsed:.2f} seconds”)
print(f”Average per URL: {elapsed/len(urls):.2f} seconds”)
successful = [r for r in results if “error” not in r]
print(f”Successful: {len(successful)}/{len(urls)}”)
# Save results
with open(“scraped_results.json”, “w”, encoding=”utf-8″) as f:
json.dump(results, f, indent=2, ensure_ascii=False)
print(“Results saved to scraped_results.json”)
if __name__ == “__main__”:
asyncio.run(main())
Python (benchmark.py)
import time
import asyncio
import requests
import aiohttp
URLS = [
“https://httpbin.org/delay/0.5”,
“https://httpbin.org/delay/0.5”,
“https://httpbin.org/delay/0.5”,
# Add 10-20 URLs for meaningful benchmark
]
def sync_fetch():
for url in URLS:
response = requests.get(url)
print(f”Sync: {url[:50]}… -> {response.status_code}”)
async def async_fetch():
async def fetch(session, url):
async with session.get(url) as response:
return response.status
async with aiohttp.ClientSession() as session:
tasks = [fetch(session, url) for url in URLS]
return await asyncio.gather(*tasks)
if __name__ == “__main__”:
print(“=” * 40)
print(“SYNCHRONOUS (3 URLs each taking 0.5s)”)
print(“=” * 40)
start = time.perf_counter()
sync_fetch()
sync_time = time.perf_counter() – start
print(f”Sync took: {sync_time:.2f} seconds”)
print(“\\n” + “=” * 40)
print(“ASYNCHRONOUS (3 URLs concurrently)”)
print(“=” * 40)
start = time.perf_counter()
asyncio.run(async_fetch())
async_time = time.perf_counter() – start
print(f”Async took: {async_time:.2f} seconds”)
print(f”\\nSpeedup: {sync_time / async_time:.1f}x faster!”)
- Add support for following pagination links recursively
- Implement a queue system for crawling entire websites
- Add proxy rotation to avoid IP bans
- Store results in a SQLite database instead of JSON
- Add email notification when scraping completes
- Create a CLI with argparse for custom URL lists
- Using `requests` instead of `aiohttp` (blocks the event loop)
- Forgetting `await` before async functions
- Creating too many concurrent connections (get rate-limited)
- Not handling timeouts (scraper hangs forever)
- Ignoring `robots.txt` and rate limits
- Why is aiohttp better than requests for async scraping?
- What does `asyncio.gather()` do?
- How do you limit the number of concurrent requests?
- What is the purpose of the semaphore in the rate-limited scraper?
- How would you add a pause between requests to be polite?
⚡ Whisper
You started with synchronous scrapers. Wait. Fetch. Wait. Fetch. Now you have built a concurrent scraper. Fetch 100 URLs at once. Wait once for the slowest. Compare the times. The difference is not small. It is 10x, 20x, 100x. asyncio is not magic. It is simply not waiting. While one request waits for a server, another starts. The event loop juggles them all. This is concurrency. This is efficiency. Use it for APIs, web scraping, database queries, any I/O that waits. Your code will be faster. Your users will be happier. Your servers will do more with less. Experiment complete. Now go build something that waits no more.


